[
Cost considerations
Let’s do the math with current pricing (OpenAI text-embedding-3-small at $0.02 per 1M tokens):
Embedding 50 docs per query (avg 500 tokens each) means 50 docs × 500 tokens = 25,000 tokens
Cost: 25,000 × $0.00002 = ~$0.0005 per query. At 1,000 queries per day × 30 days = ~$15 per month.
Actually pretty reasonable. But there’s a catch: latency.
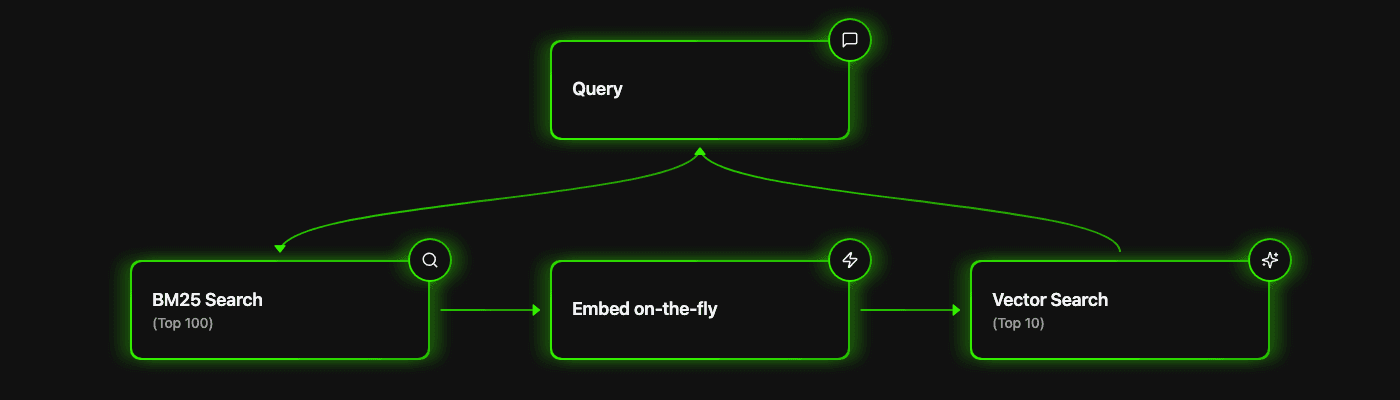
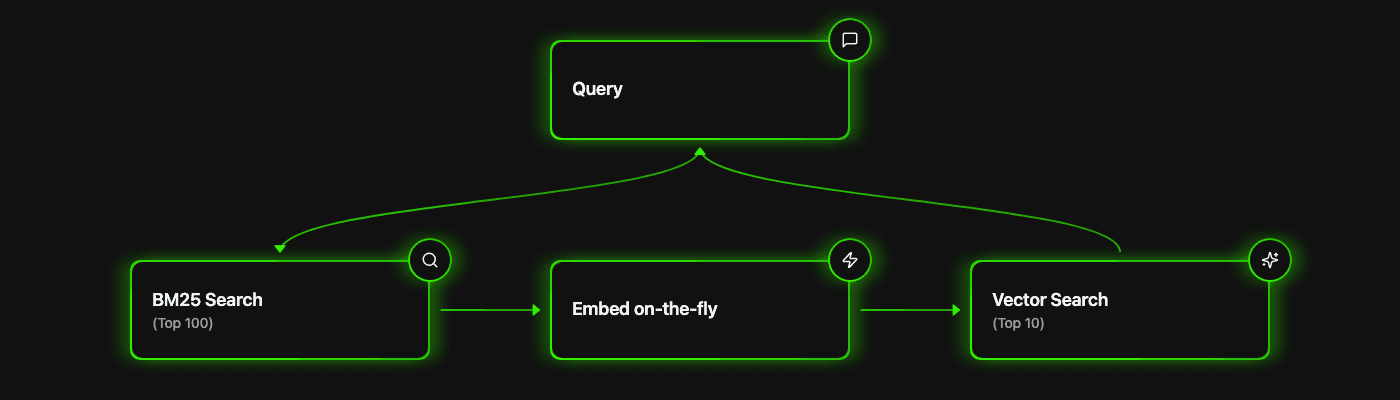
Embedding 50 documents on-the-fly adds 200-500ms per query. For user-facing search, that’s noticeable. This is where the real trade-off lives – not cost, but speed.
When you introduce embeddings, you need to decide how to chunk your documents (fixed-size? semantic? by section?). You need to determine what chunk size and overlap to use. You need to handle chunks that span important context.
This adds complexity that pure full-text search avoids.
The insight
If your data changes frequently, why pay to re-embed everything?
[
When to use
High document churn (more than 10% of docs
`On-the-fly / online (1000 queries/day, 50 docs/query):
- Embedding cost: ~$15/month (ongoing)
- Storage: $0 (just store text)
- Latency: 200-500ms per query
- Freshness: Perfect (always current)
- Model switching: Easy (just change the API call)`
The model deprecation benefit
Here’s something people don’t talk about enough: embedding models get deprecated.
OpenAI deprecated text-embedding-ada-002 in favor of text-embedding-3. If you pre-embedded 10 million documents with the old model, you now need to re-embed all 10 million documents with the new model, update your vector database, run regression tests on your evaluation set, validate that quality didn’t degrade, handle the cutover period, and deal with any API changes.
You literally just change one line of code. Done.
Latency. You’re embedding documents on every query. This is only viable if you’re okay with 200-500ms latency, K is small (reranking 20-50 docs, not 500), and your use case favors freshness over speed.
What it is
Pre-embed frequently accessed documents (”hot tier”), embed rarely-accessed documents on-the-fly (”cold tier”).
Access patterns follow Pareto distribution. 20% of docs get 80% of traffic.
`# Track access patterns access_counts = Counter()
def adaptive_search(query):
BM25 to get candidates
candidates = bm25_search(query, top_k=100)
Separate hot and cold
hot = [d for d in candidates if d.id in hot_tier] cold = [d for d in candidates if d.id not in hot_tier]
Hot docs: use pre-computed embeddings (fast)
hot_scores = vector_db.similarity_search(query_emb, hot)
Cold docs: embed on-the-fly (slower, but rare)
cold_scores = embed_and_score(cold, query_emb)
return merge_and_rank(hot_scores, cold_scores)
Periodically promote frequently accessed docs to hot tier
def update_tiers_weekly(): frequently_accessed = [doc_id for doc_id, count in access_counts.items() if count > threshold]
Only re-embed the new hot docs
newly_hot = set(frequently_accessed) - set(hot_tier) embed_and_index(newly_hot)`
When to use
Clear access patterns (some docs are accessed way more than others). Medium-to-large corpus (more than 100K documents). Mix of stable and changing content. Need good latency for common queries. Want to minimize re-embedding on model updates.
Fast for 80% of queries (hit pre-embedded cache). Fresh for rarely-accessed docs. Only re-embed hot tier when switching models (20% of corpus). Adapts to changing access patterns. Best latency/cost/flexibility trade-off.
When your embedding model gets deprecated:
Full pre-embedding: Re-embed 1M docs × $0.01 = $10,000 + downtime Hot/cold tiers: Re-embed 200K docs × $0.01 = $2,000 + minimal downtime On-the-fly: Change one line of code = $0 + zero downtime
Recipe 6: Full Pre-Embedding (The Scale Play)
What it is
Embed everything upfront. Store in vector database. Search with ANN (approximate nearest neighbors).
Very high query volume (more than 10K queries per day). Need under 50ms latency. Very stable corpus (under 5% churn per month). Access pattern is broad (no long tail). You have ML team to manage infrastructure.
`Pre-embedding (1M docs):
- One-time embedding: 1M docs × 500 tokens × $0.00002 = $10
- Storage: 1M × 1536 dims × 4 bytes = 6GB (~$10-30/month)
- Search latency: under 50ms (blazing fast!)
- Freshness: Only as fresh as last re-index`
When NOT to use
Documents change frequently (more than 10% per week). You’re experimenting with embedding models. Low query volume (under 1K queries per day). You haven’t tried simpler approaches first.
This is where full pre-embedding hurts the most. When you need to switch models, you face downtime (your search is degraded while re-embedding), compute cost (re-embedding millions of documents), testing burden (full regression test suite on new embeddings), chunking reevaluation (maybe new model works better with different chunk sizes?), and risk (what if the new model is worse for your domain?).
This is overkill for most systems. I’ve seen teams spend months optimizing their vector database setup when query rewriting would have solved 90% of their problems.
But if you’re Pinterest, Shopify, or handling massive scale with a stable corpus, this is where you end up.
Here’s where things get spicy. We’ve been discussing single-intent queries: “How do I merge dataframes?”
But real users ask stuff like: “How do I read a CSV file, clean missing data, and plot the results?”
That’s three separate intents. Searching for this as one query is like trying to find a restaurant that serves pizza, sushi, and tacos. Good luck.
Modern agentic RAG systems (Perplexity, ChatGPT search) handle this elegantly:
`# Input: “read CSV, clean data, plot results”
Agent output:
{ “query_type”: “complex”, “sub_queries”: [ “pandas read csv file”, “pandas clean missing data”, “matplotlib plot dataframe” ], “dependencies”: [“read > clean > plot”] }`
Parallel Adaptive Processing
Route each sub-query optimally
`Sub-query 1 (simple): “pandas read csv” Stopwords + lemma, then BM25 Cost: $0, Latency: 15ms
Sub-query 2 (moderate): “pandas clean missing data” Synonym expansion, then BM25 Cost: $0, Latency: 20ms
Sub-query 3 (complex): “matplotlib plot dataframe” LLM rewrite, then Multi-search Cost: $0.001, Latency: 250ms
Total (parallel): $0.002, 250ms (not 285ms!)`
Synthesize
Combine results into coherent answer
`Here’s a complete workflow:
Reading CSV Files [relevant docs from sub-query 1]
Cleaning Missing Data [relevant docs from sub-query 2]
Plotting Results [relevant docs from sub-query 3]
[Code example combining all three steps] `
Why this works
Each sub-query is focused and precise, leading to better retrieval. Parallel execution means lower latency (max, not sum). Adaptive routing results in lower cost (only complex queries pay for LLM). Structured output provides better UX.
LLM rewriting entire complex query: $0.005
This is where agentic retrieval really shines. The agent can intelligently decide which sub-queries need expensive processing (embeddings) and which can be handled with cheap methods (simple preprocessing + BM25).
Okay, you’ve read this far. You just want to know: “What should I build?”
Start here: Do you have search at all? If not, build BM25 first. Seriously. Stop reading and build it. If you do have search, continue.
Measure your baseline. Run your current search for 2-4 weeks and collect user feedback. Are users happy with the results? If yes, stop. You’re done. Go ship features. If no, continue.
If users say “Can’t find docs that clearly exist,” try query rewriting first. At $0.001 per query with zero re-indexing, it’s worth testing. Run an A/B test for 2 weeks. If you see good improvement, keep it and you’re done. If it’s not enough, continue.
If users say “Results are okay but not great,” A/B test hybrid search (sparse plus embedding rerank). Is the added latency worth it? If yes, decide on implementation. If your data changes frequently, use on-the-fly embedding. If you have clear hot docs, use hot/cold tiers. If you have a stable corpus and high scale, use full pre-embedding. If the latency isn’t worth it, optimize query rewriting further instead.
If users say “Need better semantic understanding,” use hybrid search and choose your approach based on your situation. High churn (more than 10% per day) means on-the-fly. Medium scale with clear patterns means hot/cold tiers. Massive scale with stable data means full pre-embedding.
Full-text with query rewriting offers perfect data freshness with low setup complexity and query latency under 50ms. Model switching is trivial, no chunking is needed, and it works for most use cases.
On-the-fly embedding provides perfect data freshness with low setup complexity but higher query latency of 200-500ms. Model switching is trivial, chunking is needed, and it’s best for high churn scenarios.
Hot/cold tiers provide mixed data freshness with medium setup complexity and query latency of 50-100ms. Model switching is easy, chunking is needed, and it offers balanced performance for varied needs.
Full pre-embedding has stale data until reindex with high setup complexity but query latency under 50ms. Model switching is painful, chunking is needed, and it’s designed for massive scale operations.
The 80/20 rule: 60% of systems should stop at full-text plus query rewriting. 25% need hybrid with on-the-fly or hot/cold. 10% need full pre-embedding. 5% need custom solutions.
Bottomline: Don’t be the person who builds the 5% solution for a 60% problem.
Thanks for reading Lighthouse Newsletter! Subscribe for free to receive new posts and support my work.
4
5
Share
PreviousNext
Comments

Lighthouse AI reply rules
TopLatest
No posts
Start your SubstackGet the app
Substack is the home for great culture
window.__staticRouterHydrationData = JSON.parse("{"loaderData":{},"actionData":null,"errors":null}");
window.Sentry && window.Sentry.onLoad(function() { window.Sentry.init({ environment: window._preloads.sentry_environment, dsn: window._preloads.sentry_dsn, }) })
window.preloads = JSON.parse("{"cspNonce":"SAcmJ7NWg-H1ESh_1FWxIA","isEU":false,"language":"en-gb","country":"JP","leaderboardCountries":["ES","FR","GB","IT","NL"],"enabledLeaderboardCountries":["ES","FR","GB","IT","NL"],"userLocale":{"language":"en","region":"US","source":"default"},"base_url":"https://www.lighthousenewsletter.com","stripe_publishable_key":"pk_live_51QfnARLDSWi1i85FBpvw6YxfQHljOpWXw8IKi5qFWEzvW8HvoD8cqTulR9UWguYbYweLvA16P7LN6WZsGdZKrNkE00uGbFaOE3","captcha_site_key":"6LeI15YsAAAAAPXyDcvuVqipba_jEFQCjz1PFQoz","pub":{"apple_pay_disabled":false,"apex_domain":"lighthousenewsletter.com","author_id":528382322,"byline_images_enabled":true,"bylines_enabled":true,"chartable_token":null,"community_enabled":true,"copyright":"LLM HOWTO BV","cover_photo_url":"https://substack-post-media.s3.amazonaws.com/public/images/6894edcc-0123-4a6a-9717-0766c172db25_1280x722.png","created_at":"2026-07-12T10:37:03.757Z","custom_domain_optional":false,"custom_domain":"www.lighthousenewsletter.com","default_comment_sort":"best_first","default_coupon":null,"default_group_coupon":"8f653fa6","default_show_guest_bios":true,"email_banner_url":null,"email_from_name":"Rafael from Lighthouse AI","email_from":null,"embed_tracking_disabled":false,"explicit":false,"expose_paywall_content_to_search_engines":true,"fb_pixel_id":null,"fb_site_verification_token":null,"flagged_as_spam":false,"founding_subscription_benefits":["Lifetime access to all posts, webinars, plus all other benefits from the other tiers"],"free_subscription_benefits":["Occasional public posts"],"ga_pixel_id":null,"google_site_verification_token":null,"google_tag_manager_token":null,"hero_image":null,"hero_text":"Notes on how engineering shapes production AI, and how AI is reshaping engineering.","hide_intro_subtitle":null,"hide_intro_title":null,"hide_podcast_feed_link":false,"homepage_type":"magaziney","id":9986181,"image_thumbnails_always_enabled":false,"invite_only":false,"hide_podcast_from_pub_listings":false,"language":"en-gb","logo_url_wide":null,"logo_url":"https://substackcdn.com/image/fetch/$s!rokM!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fa95a4828-fc18-47b5-bda3-712b30c06098_1024x1024.png","minimum_group_size":2,"moderation_enabled":false,"name":"Lighthouse AI","paid_subscription_benefits":["Webinars","Post comments and join the community","Subscriber-only posts and full archive"],"parsely_pixel_id":null,"chartbeat_domain":null,"payments_state":"disabled","paywall_free_trial_enabled":false,"podcast_art_url":null,"paid_podcast_episode_art_url":null,"podcast_byline":null,"podcast_description":null,"podcast_enabled":false,"podcast_feed_url":null,"podcast_title":null,"post_preview_limit":null,"primary_user_id":null,"require_clickthrough":false,"show_pub_podcast_tab":false,"show_recs_on_homepage":true,"subdomain":"lighthousenewsletter","subscriber_invites":0,"support_email":null,"theme_var_background_pop":"#FF6719","theme_var_color_links":false,"theme_var_cover_bg_color":null,"trial_end_override":null,"twitter_pixel_id":null,"type":"newsletter","post_reaction_faces_enabled":true,"is_personal_mode":false,"plans":null,"stripe_user_id":"acct_1U3uq9LDxLmnOL0O","stripe_country":"NL","stripe_publishable_key":"pk_live_51U3uq9LDxLmnOL0OyASOSZIM7ltDTNzxp8D6RlbYle8fUqOUyt1WhJ7d4EUPD4u4RJyl4BP5QqhAkXT99Uv5R21W00v87cmpSM","stripe_platform_account":"US","automatic_tax_enabled":false,"author_name":"Rafael Pierre","author_handle":"rafaelpierre","author_photo_url":"https://substackcdn.com/image/fetch/$s_!eVfY!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F1d9eecca-8732-465d-a8b3-2277827977d8_800x800.png","author_bio":"Ex-Hugging Face / Databricks. If you like my writing, I encourage you to subscribe to my newsletter Lighthouse AI, as well as liking, commenting and sharing my posts. All views are exclusively my own.","has_custom_tos":false,"has_custom_privacy":false,"theme":{"background_pop_color":"#000000","web_bg_color":"#ffffff","cover_bg_color":"#ffffff","publication_id":9986181,"color_links":null,"font_preset_heading":null,"font_preset_body":null,"font_family_headings":null,"font_family_body":null,"font_family_ui":null,"font_size_body_desktop":null,"print_secondary":null,"custom_css_web":null,"custom_css_email":null,"home_hero":"feature","home_posts":"custom","home_show_top_posts":false,"hide_images_from_list":false,"home_hero_alignment":"left","home_hero_show_podcast_links":true,"default_post_header_variant":null,"custom_header":{"layout":"logo_left","navStyle":"text","wordmarkLogoSize":24},"custom_footer":{"layout":"two-column","backgroundColor":null,"publicationNameSize":50,"showPublicationName":true,"publicationNameStyle":"text","publicationNamePosition":"bottom","publicationNameBackgroundColor":null},"social_media_links":{"linkedin":null},"font_options":{"body":"roboto_mono_400","heading":"roboto_mono_700","wordmark":"roboto_mono_700"},"section_template":null,"custom_subscribe":null,"design_template":null,"design_template_options":null},"threads_v2_settings":{"first_thread_email_sent_at":null,"activated_at":null,"reader_thread_notifications_enabled":false,"create_thread_minimum_role":"contributor","photo_replies_enabled":false,"boost_free_subscriber_chat_preview_enabled":false,"push_suppression_enabled":false},"default_group_coupon_percent_off":"10.00","default_group_coupon_include_founding":true,"pause_return_date":null,"has_posts":true,"has_recommendations":true,"first_post_date":"2025-09-07T20:17:00.522Z","has_podcast":false,"has_free_podcast":false,"has_subscriber_only_podcast":false,"has_community_content":false,"rankingDetail":null,"rankingDetailFreeIncluded":null,"rankingDetailOrderOfMagnitude":null,"rankingDetailFreeIncludedOrderOfMagnitude":null,"rankingDetailFreeSubscriberCount":null,"rankingDetailByLanguage":{},"freeSubscriberCount":null,"freeSubscriberCountOrderOfMagnitude":null,"author_bestseller_tier":0,"author_badge":null,"disable_monthly_subscriptions":false,"disable_annual_subscriptions":false,"hide_post_restacks":false,"notes_feed_enabled":true,"showIntroModule":false,"isPortraitLayout":false,"last_chat_post_at":null,"no_follow":false,"sponsorshipCampaigns":{},"paywall_chat":"free","sections":[{"id":449943,"created_at":"2026-08-26T10:22:56.343Z","Nowadays, most people seem to over-engineer their RAG stack. They jump straight to embeddings, vector databases, and reranking pipelines. Meanwhile, their users just want to find the doc that says \u201CHow to reset my password.\u201D
In engineering, there\u2019s always the right tool for the right problem. In AI Retrieval Systems it\u2019s not different.
Before we dive into recipes, let\u2019s establish when you should use each approach. The key factors are:
1. Data Freshness Requirements - Real-time updates (news, social media) favor approaches with easy re-indexing. Daily or weekly updates work well with hybrid approaches. A stable corpus (monthly or quarterly updates) makes pre-embedding sensible.
2. Corpus Characteristics - High churn (more than 10% changes daily) means you should avoid full pre-embedding. Stable documents work fine with pre-embedding. Long-tail distribution (90% never accessed) means on-the-fly wins.
3. Query Patterns - Keyword-heavy queries should start with full-text search. Semantic or conversational queries benefit from embeddings. Mixed patterns need hybrid approaches.
4. Scale & Performance - Less than 1000 queries per day means simple approaches are sufficient. 1K to 10K queries per day requires selective optimization. More than 10K queries per day justifies full optimization.
5. Team Capabilities - No ML expertise means stay with full-text plus query rewriting. Some ML experience makes hybrid search manageable. Having an ML team available makes advanced approaches viable.
Now, let\u2019s look at the recipe book. Start at the top. Move down only when you have data proving you need to.
Good old BM25. Elasticsearch. Postgres full-text search. The stuff that existed before \u201Cembedding\u201D became a verb.
You\u2019re just starting out. Your users write keyword-style queries (\u201Dpandas merge dataframe\u201D). Exact matches matter (\u201Dinvoice #12345\u201D). You want zero ML complexity. Your corpus has proprietary terminology (more on this later).
Zero API costs. Fast (under 10ms). Easy to debug (you can see exactly why a document matched). Surprisingly effective (handles many use cases). No chunking strategy needed \u2013 works with full documents. No evaluation complexity \u2013 easy to test and validate. No model deprecation risk (BM25 doesn\u2019t change).
Misses synonyms (\u201Dcar\u201D vs \u201Cautomobile\u201D). Fails on semantic queries (\u201DHow do I…?\u201D). Can\u2019t understand intent beyond keywords.
In my experience, this handles a significant portion of use cases. Don\u2019t skip this step. You might be surprised how far you can get.
When you jump straight to embeddings, you immediately face questions like: What chunk size? (512 tokens? 1024?) What overlap? (50 tokens? 100?) Semantic chunking or fixed-size? How do I evaluate if my chunking is good?
With full-text search, you skip all of this. Your documents are your documents. Search just works.
Use an LLM to transform messy user queries into clean keyword searches.
Most \u201Csemantic search\u201D problems are actually query formulation problems.
When to use
Users ask questions conversationally. Vocabulary mismatch (users say \u201Cfix bugs\u201D, docs say \u201Cdebugging\u201D). You have internal jargon (your framework called \u201CAtlas\u201D). You want flexibility to iterate quickly on query strategies.
~$0.001 per query (using GPT-4o-mini for query rewriting)
An LLM can remove stopwords (\u201Dhow do I\u201D becomes nothing). It can add synonyms (\u201Dcar\u201D becomes \u201Ccar automobile vehicle\u201D). It can translate domain terms (\u201Dspeed up code\u201D becomes \u201Coptimize performance\u201D). It can decompose complex queries (\u201Dread CSV and plot\u201D becomes [\u201Dread CSV\u201D, \u201Cplot data\u201D]). It can learn from your glossary (via system prompt).
With embeddings, if results aren\u2019t good, you need to adjust chunking strategy, re-embed entire corpus, run regression tests on your eval set, and hope it improved.
With query rewriting, if results aren\u2019t good, you adjust the system prompt. That\u2019s it. Test immediately.
def agentic_search(query, max_iterations=3):\\n for i in range(max_iterations):\\n # Rewrite query\\n optimized = query_rewriter.rewrite(query, iteration=i)\\n \\n # Search\\n results = bm25_search(optimized)\\n \\n # Evaluate quality\\n quality = evaluate_results(results, query)\\n \\n if quality > threshold:\\n return results\\n \\n # Agent learns and tries again\\n query = refine_based_on_feedback(query, results, quality)\\n \\n return results
The agent can iterate, learn, and adapt \u2013 all without re-embedding anything.
Say your company has a Python framework called \u201CAtlas.\u201D If you use general-purpose embeddings:
General embedding model (trained on internet):\\n\u201CAtlas\u201D = [vectors pointing toward: Greek mythology, maps, geography]\\nYour actual Atlas docs = [vectors about data processing]\\nSimilarity score: 0.15 (terrible!)The model has no idea your \u201CAtlas\u201D exists. It falls back to what it learned in training. But with query rewriting:
system_prompt = \\\"\\\"\\\"\\n Domain-specific terms (NEVER modify these, use as exact keywords):\\n - Atlas: our internal data processing framework\\n - Mercury: our messaging system\\n - Zeus: our auth service\\n\\n Preserve these terms exactly and optimize the rest of the query.\\n\\\"\\\"\\\"\\n\\n# User: \\\"How do I use Atlas for batch jobs?\\\"\\n# Agent: \\\"Atlas batch jobs data processing pipeline\\\"\\n# BM25: Perfect match on \\\"Atlas\\\" \u2713
For proprietary terms, exact keyword matching beats semantic understanding.
Thanks for reading Lighthouse AI! Subscribe for free to receive new posts and support my work.
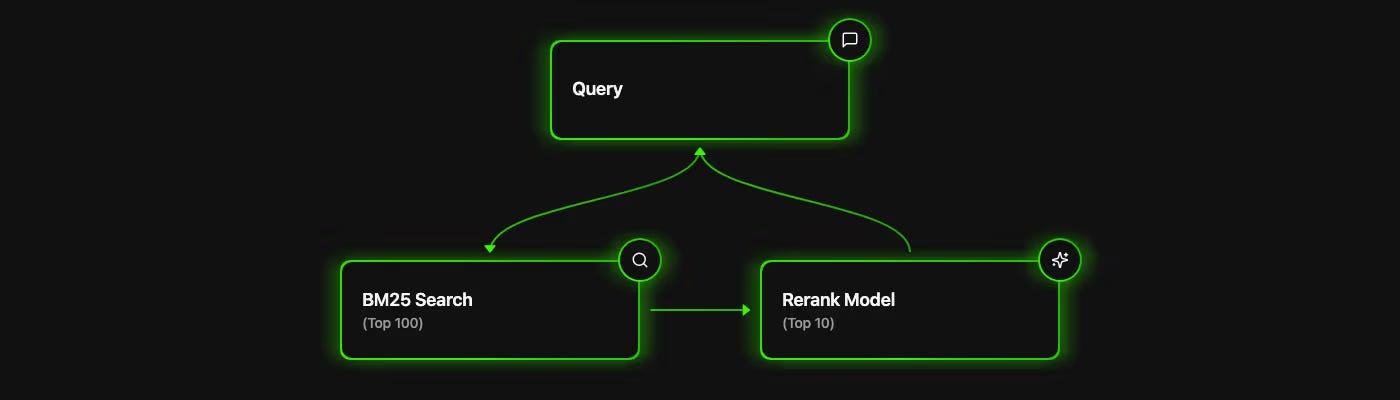
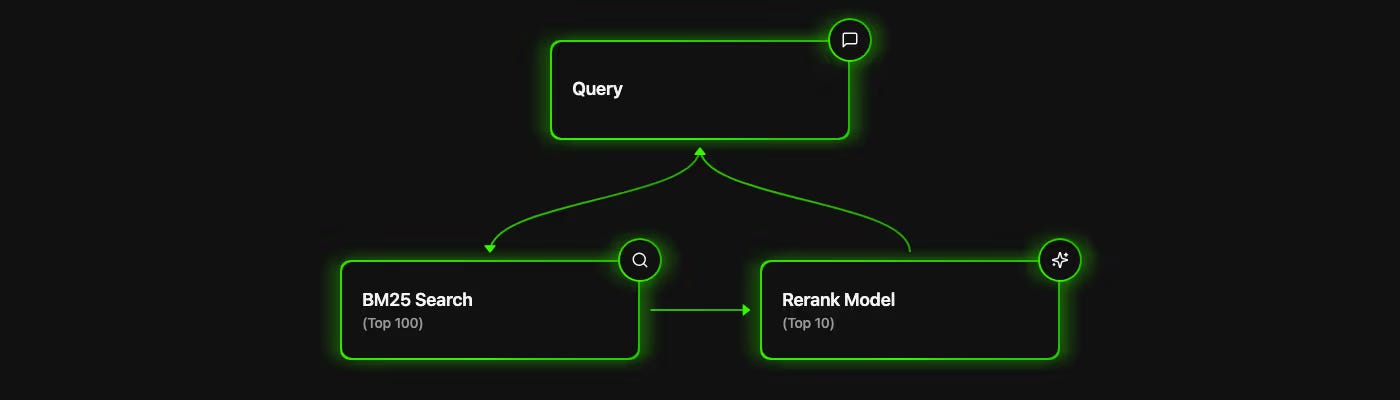
Use BM25 to get candidates (top 50-100), then rerank with embeddings (top 10).
BM25 is fast and great at keyword matching. Embeddings are good at semantic understanding. Together, they cover each other\u2019s weaknesses.
Users ask semantic questions (\u201Dfind alternatives to X\u201D). BM25 plus query rewriting alone isn\u2019t cutting it (you have data proving this). You can tolerate 100-500ms latency. Your corpus is relatively stable (not changing every minute).
Cost considerations
Let\u2019s do the math with current pricing (OpenAI text-embedding-3-small at $0.02 per 1M tokens):
Embedding 50 docs per query (avg 500 tokens each) means 50 docs \u00D7 500 tokens = 25,000 tokens
Cost: 25,000 \u00D7 $0.00002 = ~$0.0005 per query. At 1,000 queries per day \u00D7 30 days = ~$15 per month.
Actually pretty reasonable. But there\u2019s a catch: latency.
Embedding 50 documents on-the-fly adds 200-500ms per query. For user-facing search, that\u2019s noticeable. This is where the real trade-off lives \u2013 not cost, but speed.
When you introduce embeddings, you need to decide how to chunk your documents (fixed-size? semantic? by section?). You need to determine what chunk size and overlap to use. You need to handle chunks that span important context.
This adds complexity that pure full-text search avoids.
If your data changes frequently, why pay to re-embed everything?
When to use
High document churn (more than 10% of docs
On-the-fly / online (1000 queries/day, 50 docs/query):\\n- Embedding cost: ~$15/month (ongoing)\\n- Storage: $0 (just store text)\\n- Latency: 200-500ms per query\\n- Freshness: Perfect (always current)\\n- Model switching: Easy (just change the API call)
The model deprecation benefit
Here\u2019s something people don\u2019t talk about enough: embedding models get deprecated.
OpenAI deprecated text-embedding-ada-002 in favor of text-embedding-3. If you pre-embedded 10 million documents with the old model, you now need to re-embed all 10 million documents with the new model, update your vector database, run regression tests on your evaluation set, validate that quality didn\u2019t degrade, handle the cutover period, and deal with any API changes.
You literally just change one line of code. Done.
Latency. You\u2019re embedding documents on every query. This is only viable if you\u2019re okay with 200-500ms latency, K is small (reranking 20-50 docs, not 500), and your use case favors freshness over speed.
Pre-embed frequently accessed documents (\u201Dhot tier\u201D), embed rarely-accessed documents on-the-fly (\u201Dcold tier\u201D).
Access patterns follow Pareto distribution. 20% of docs get 80% of traffic.